LIFE SCIENCES
The instruments got faster. The transfer didn't.
A single sequencing run, an imaging session, a screening campaign – each produces datasets measured in hundreds of gigabytes or terabytes, and each one has somewhere to be. Analysis compute. A collaborator. A sponsor. A patient. An archive.
The methods available are all compromised in some way. FTP is slow across distance and fails without warning on long transfers. Consumer file sharing caps out well below a single run. Shipping drives introduces days of latency and a chain of custody problem. And a third-party cloud transfer service adds a processor to your data flow, which means a security review, a contract, and an answer to where exactly the data sits while in transit.
That last problem gets harder, not easier, when the transfer crosses an organizational boundary. Sponsor to Clinical Research Organization (CRO), provider to customer, site to partner lab: two sets of policies, two security teams, and data that neither side particularly wants sitting on someone else's infrastructure.
Your servers on both ends. Nothing in the middle.
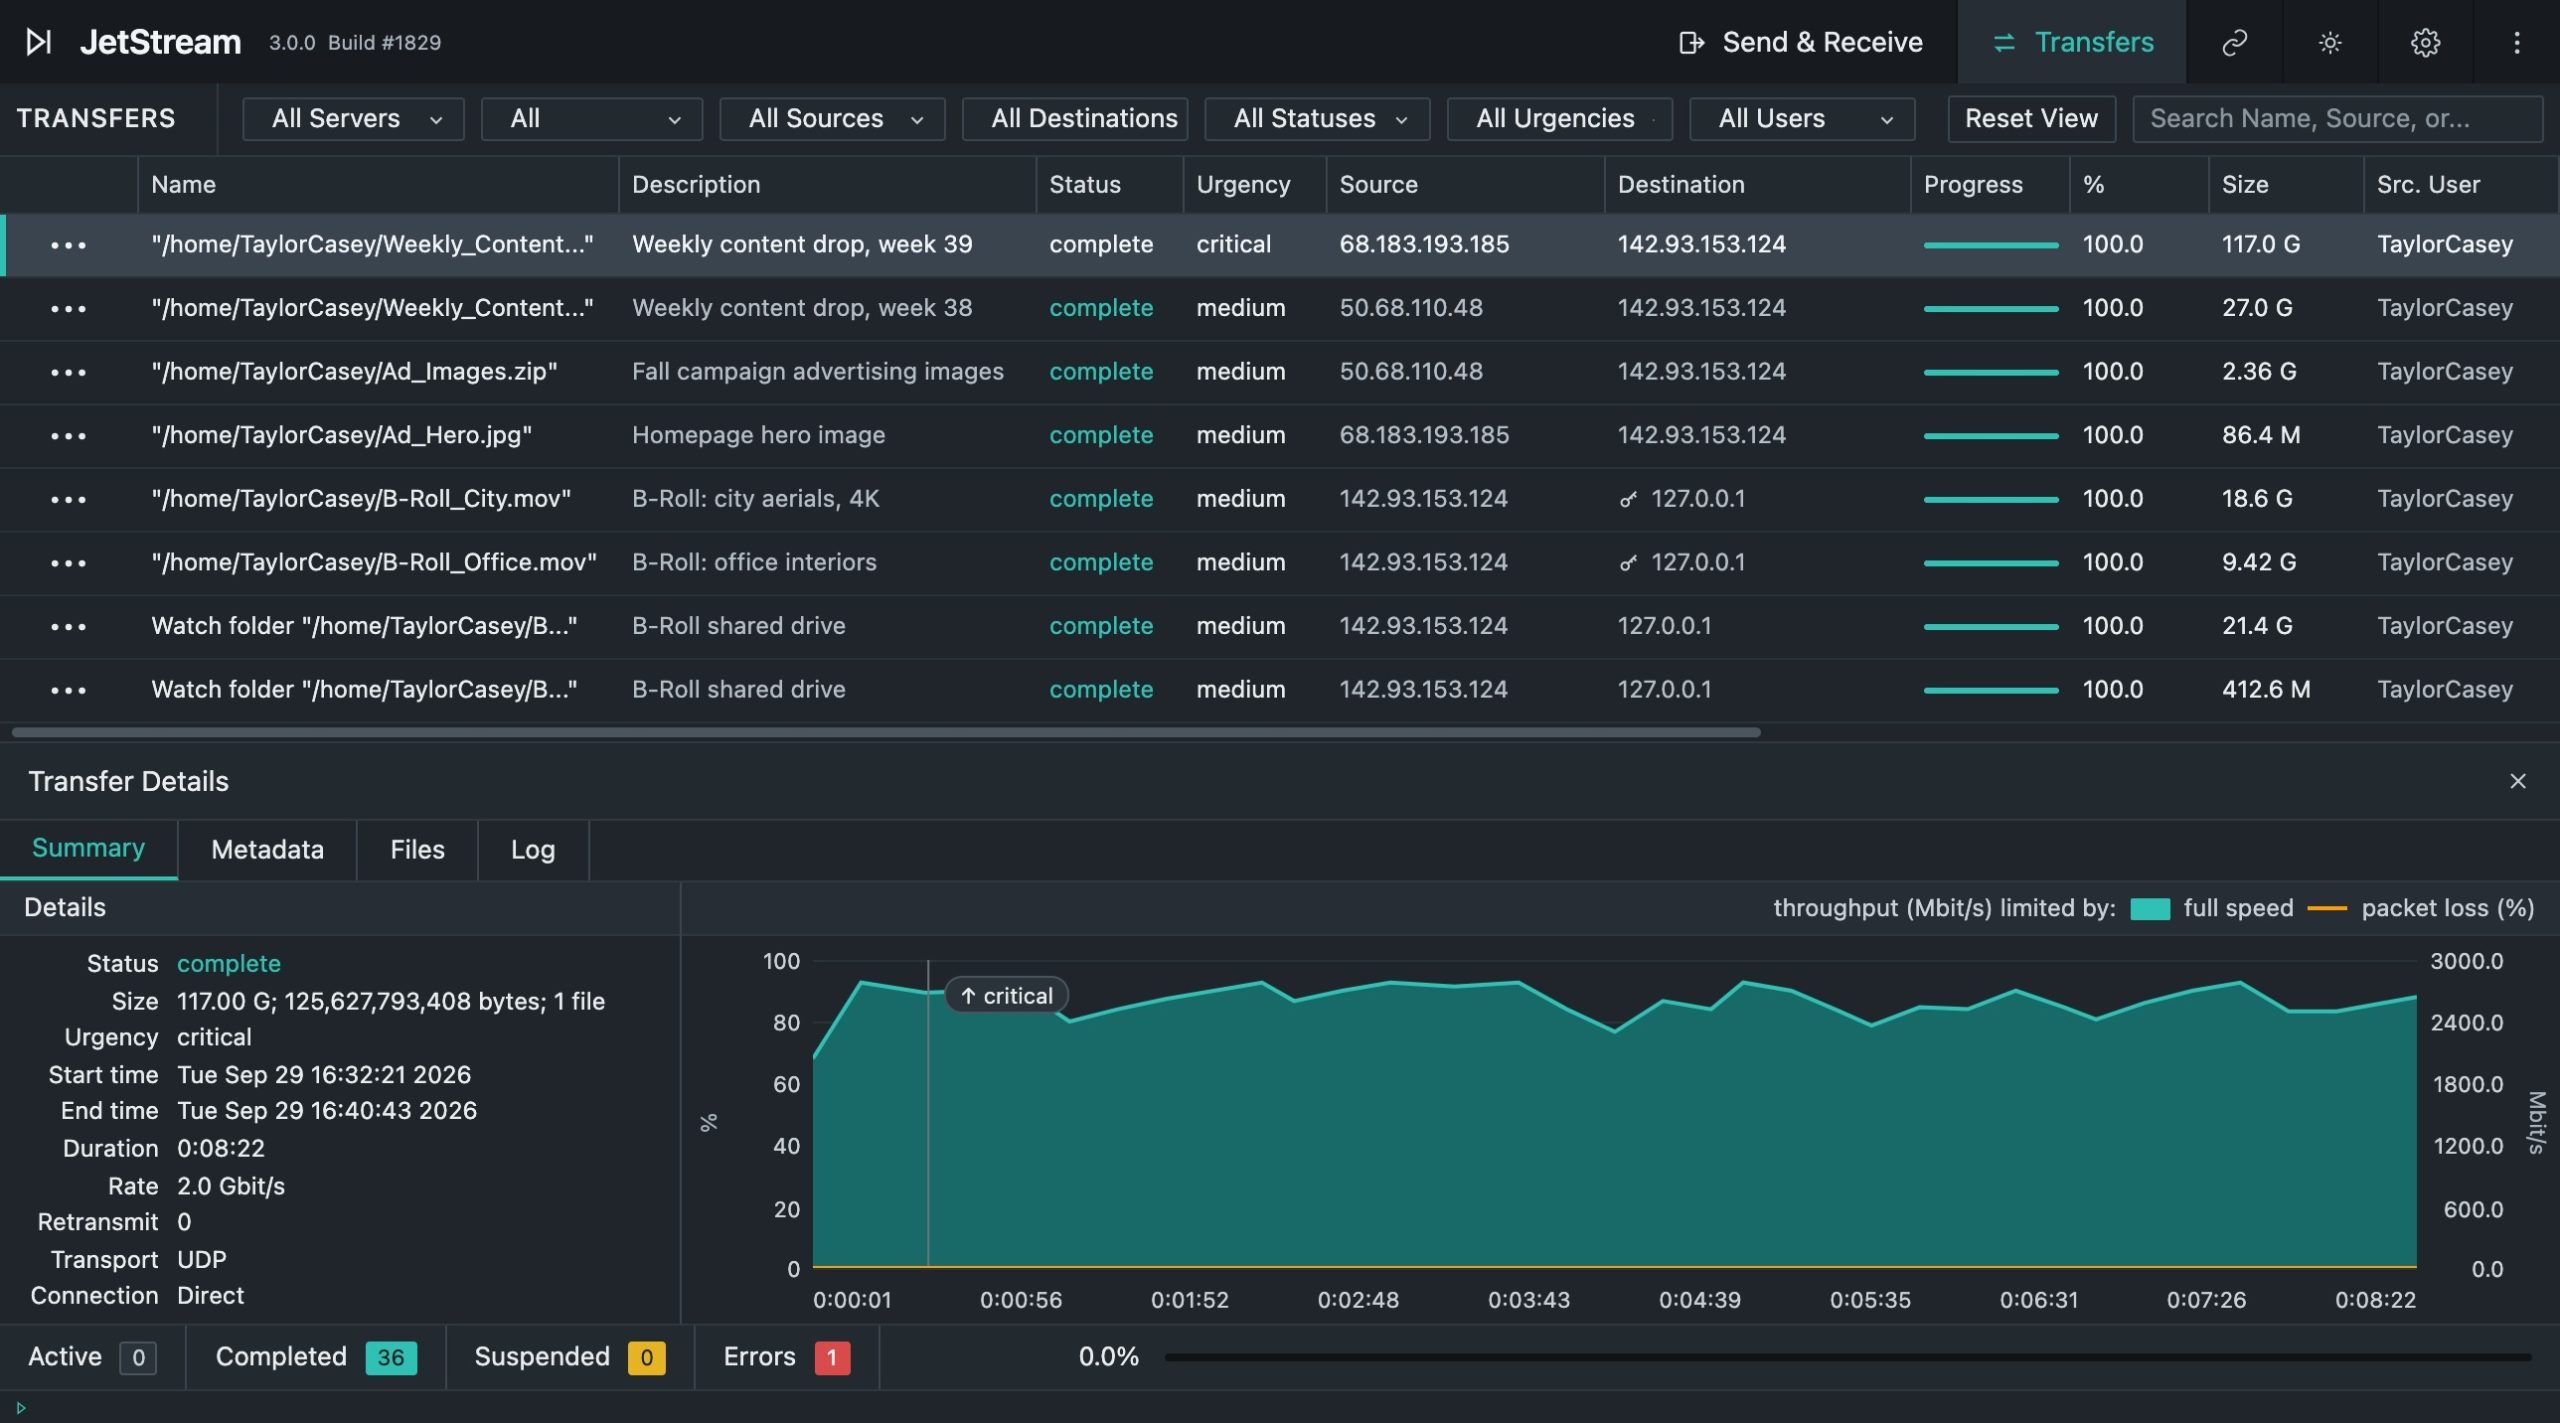
JetStream is deployed on infrastructure you already control: on-premise, or in your own cloud account. Data moves point-to-point between your systems over a custom UDP protocol at whatever speed the network allows.
There is no intermediary service holding your data in transit, which means no new processor to assess, no third-party data residency question, and no dependency on a vendor's cloud footprint matching your policy. The controls you already run (your directory, your network segmentation, your storage governance) apply to JetStream transfers because the transfers happen inside them.
Predictable cost. Unchanged perimeter.
Nothing leaves your environment.
JetStream runs on your infrastructure at both ends. No file passes through a vendor-operated service, so the transfer path stays inside the security envelope your organization has already defined and assessed.
Encryption and authentication you already recognize.
AES-256/GCM at the transfer level and TLS 1.3 on the server connection. Authenticate against PAM, Active Directory, or LDAP, sandbox users to specific directories, and exclude file types from transferring entirely.
Cost that doesn't scale with data.
Licensing is per server, not per seat and not per gigabyte. A heavy sequencing month costs the same as a quiet one, which matters when volume is driven by instrument throughput rather than budget planning.
Every collaborator, no extra license.
The client application can be distributed to partner labs, CROs, and service providers at no cost. Adding an organization to a project has no licensing consequence.
Integrity on every transfer.
Configurable MD5 checking verifies transfers on the fly or by file, and interrupted transfers resume from where they stopped rather than starting over.
How do you transfer terabytes of data between organizations?
Point-to-point, with a transfer server at each end. JetStream is deployed on infrastructure each organization already controls, and data moves directly between them over an accelerated file transfer protocol without passing through an intermediary service. Transfers resume from the point of interruption if a connection drops.
Does JetStream store our data?
No. JetStream is software you deploy on your own servers or in your own cloud account. Files move directly between your systems and your partners' systems. There is no vendor-operated service in the transfer path holding your data.
How does JetStream handle very large numbers of files?
Concurrent transfers can run to a single destination on a single port, and Watch Folders preserve source folder structure end to end. Datasets made up of many files transfer without zipping and arrive organized as they left.
Can transfers be automated into an existing pipeline?
Yes. Watch Folders trigger transfers on file arrival, and the open API is published online and included at no additional cost, so transfers can be built into an existing analysis or archive workflow rather than run by hand.
How is JetStream priced for high-volume data?
Per server, not per gigabyte and not per seat. Transfer volume, bandwidth, and the number of users are uncapped, so cost does not rise with instrument throughput.